AI Agent Testing Needs a Crash-Test Facility

The uncomfortable truth about AI agent testing is that most companies are testing a presentation, not a product. A clean demo proves the agent can complete a prepared task. It says almost nothing about what happens after two employees update the same account, a permission expires, or another system holds conflicting information.
That distinction matters because enterprise work is messy by default. Records drift. People use tools differently. A process that looks linear in a diagram often crosses several systems and depends on unwritten judgment.
However, many teams still evaluate agents with happy-path prompts and a handful of successful runs. Then they grant the agent access to customer data, internal workflows, or financial actions. At that point, customers become the test environment.
AI Agent Testing Needs Repeatable Reality
TechCrunch reported that Arga Labs raised $10 million to build digital twins of enterprise software. These environments preserve permissions, webhooks, and application state. Teams can reset them and run the same scenario thousands of times.
The funding is interesting. The operating lesson is more important.
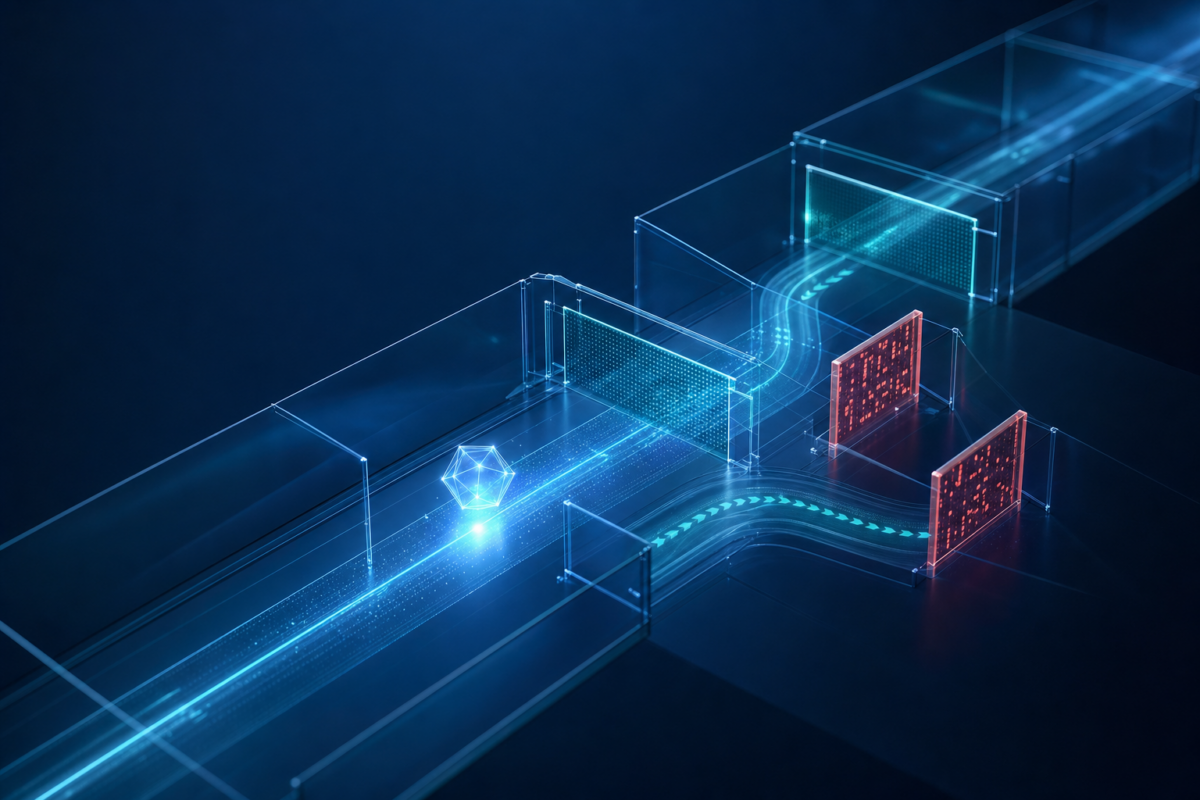
Enterprise agents need a crash-test facility. A stateless API sandbox cannot reveal how an agent behaves when one system says a lead is new and another says a colleague already contacted it. It also cannot show whether the agent notices duplicate records or respects a mid-workflow permission change.
Traditional software testing assumes a known input should produce a known output. Agents make that model less useful. They interpret incomplete context, choose actions, and change the environment that informs their next choice.
Therefore, the test must include the environment itself.
The Failure Lives Between Systems
Most agent failures will not come from an obviously broken model. Instead, they will come from reasonable actions based on incomplete or stale state.
Imagine an agent assigned to follow up with a sales lead. The CRM shows no recent activity. Meanwhile, an email system shows that another employee replied ten minutes ago. The agent can follow its instructions perfectly and still annoy the prospect with a duplicate message.
That is a business failure, not a benchmark failure.
Building software for support teams has taught me that the hardest problems often sit between the official workflow and the way people actually work. A ticket may look resolved while the customer remains stuck. Likewise, an agent may report success because it completed an action, even though the action made the broader situation worse.
I have written before about the danger of agents closing tickets without understanding the outcome. The same principle applies across enterprise software. Completion is not the same as correctness.
Stop Testing Prompts in Isolation
Weak AI agent testing asks, “Did the model answer correctly?”
Strong testing asks, “Did the entire workflow end in an acceptable state?”
That means operators must test permissions, timing, conflicting records, and interrupted work. They should also test what happens when the agent encounters an unfamiliar condition. Does it pause? Does it ask for help? Or does it confidently force the workflow toward completion?
The last behavior is especially dangerous. An agent that fails loudly creates a support problem. An agent that fails quietly creates bad data and false confidence.
Consequently, prompt evaluations cannot carry the full burden. They help teams compare instructions or model versions. Yet they do not reproduce the state changes that make production systems unpredictable.
A resettable environment changes the economics. Teams can replay the same incident after updating a prompt, policy, integration, or model. As a result, they can determine whether a fix solved the original problem or merely changed its shape.
Turn Real Incidents Into Test Scenarios
Operators already have much of the raw material needed for better AI agent testing. It sits in support tickets, audit logs, escalation notes, and customer complaints.
Whenever an agent makes a costly mistake, the team should convert that failure into a repeatable scenario. Then every future version must pass it before deployment.
Software teams already treat regression tests this way. Agent teams should adopt the same discipline, although the scenarios need richer state. A useful case includes what each system knew, what permissions existed, and what changed while the agent worked.
For example, a billing agent should face more than a clean refund request. Test duplicate subscriptions, partial credits, expired authorization, and contradictory account notes. More importantly, test whether the agent recognizes when policy does not cover the situation.
Over time, this scenario library becomes a valuable company asset. It captures operational knowledge that rarely appears in process documentation.
Measure Recovery, Not Only Accuracy
No realistic test program will make an autonomous agent perfect. So the next question is whether the system fails safely.
Good AI agent testing should measure escalation quality and recovery cost. When uncertain, does the agent preserve context for a human? Can the team reverse its actions? Does the system show why the agent made a decision?
These questions sound less exciting than model accuracy. However, they matter more to an operator responsible for customers and revenue.
A cautious agent may complete fewer tasks without help. Still, that can be the better business outcome. One avoided billing mistake can outweigh hundreds of fully automated routine actions.
Therefore, success metrics should include the cost of correction. If a human needs thirty minutes to reconstruct what happened, the agent did not save the full amount of time shown on the automation dashboard.
Autonomy Has a Testing Cost
A company should not grant broad autonomy simply because an agent can perform a task. It should first ask whether that autonomy is worth testing and maintaining.
Low-impact, reversible actions need lighter controls. High-impact actions require deeper environments, stricter approval rules, and continuous regression testing. This raises the real cost of automation.
That cost may still be justified. However, leaders should include it in the decision from the beginning. Otherwise, an inexpensive pilot turns into an expensive operational liability.
The practical rule is simple: the wider the agent’s authority, the more realistic its test environment must become.
This also clarifies ownership. AI agent testing cannot belong only to the team that built the integration. Operations knows the exceptions. Support sees customer harm first. Security understands permission boundaries. Product must decide which failures are acceptable.
Someone must combine that knowledge into deployment gates with authority to stop a release.
Build the Crash-Test Facility Before the Highway
The Arga Labs story signals a useful shift. Enterprise AI is moving past impressive task demos and toward the less glamorous work of proving reliability under pressure.
Operators should welcome that shift. The companies that benefit from agents will not be the ones with the most polished demo. They will be the ones that can reproduce ambiguity before it reaches a customer.
Before giving an agent more authority, build the environment where it can fail repeatedly, safely, and visibly. If you cannot reproduce the failure, you are not ready to automate the decision.